
📌 本文重點
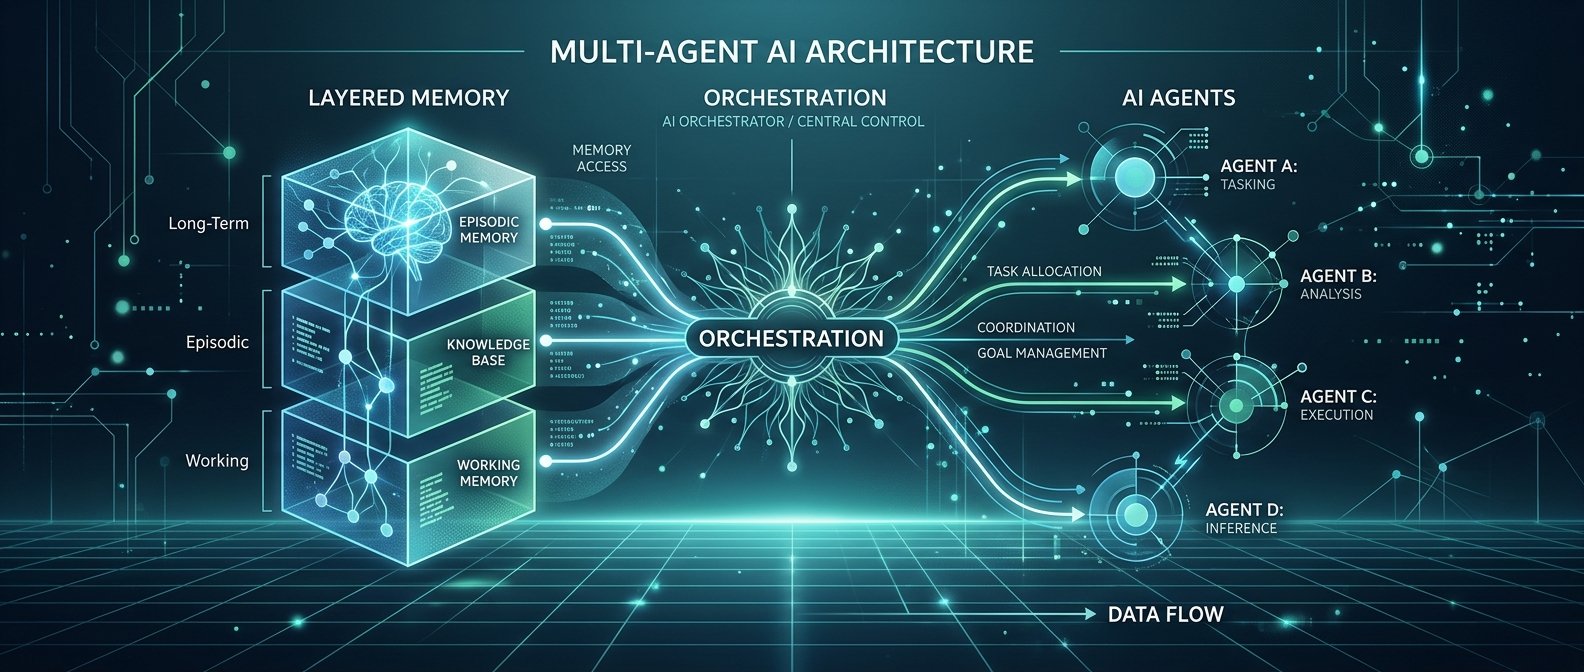
- 企業優先採集中式 Orchestrator 架構
- 機構記憶分層是合規與治理核心
- 推理層治理讓多代理決策可追溯
斯坦福用約 37,000 個生命科學 AI Agent 模擬完整藥物研發流程,背後其實解決了幾個你在企業落地多代理系統時一定會遇到的痛點:
- 大量 Agent 的角色分工與任務編排很容易失控變成「亂聊」與重複計算。
- 上下文與機構記憶(Institutional Memory)若沒設計好,結果不是錯就是無法追溯責任。
- 沒有推理層治理(reasoning-layer governance),就算所有 Agent 都有 log,也很難回答:這個決策到底是怎麼被做出來、誰負責。
下面從架構到治理拆解這個案例,並給出可以直接套用到企業內的大規模 Agent 實作建議。
重點說明
1. 多代理架構:集中式 Orchestrator vs 去中心化協作
在斯坦福案例與企業場景中,你大致有兩種架構選擇:
- 集中式 Orchestrator:一個核心服務(或少數幾個)負責:
- 任務分解:把「藥物發現」拆成靶點鑑定、ADMET 分析、臨床試驗設計等子任務。
- Agent 指派:依角色與技能分配任務。
- 結果整合與審核:負責決策鏈的組裝與治理介面。
- 去中心化協作:各 Agent 透過共享記憶與協作協議自行形成工作流,例如:
ProjectAgent發起任務。DomainAgent(臨床統計、藥理學、法規)透過訂閱特定Topic自主加入。
實務建議:
- 在企業內落地大規模 Agent,90% 情況先用集中式 Orchestrator,因為:
- 權限、合規與審核路徑好管控。
- 錯誤與成本可聚焦在少數 orchestrator 節點。
- 去中心化協作比較適合:
- 研究環境或內部沙盒。
- 對容錯要求高、但對審核延遲容忍度也高的場景。
💡 關鍵: 企業導入多代理系統時,集中式 Orchestrator 能在 90% 場景中兼顧效率與合規,是安全的預設架構選擇。
2. 機構記憶與上下文管理:從「文件庫」變成「治理介面」
V7 的作法很關鍵:用 GPT-5.6 建構機構記憶層,讓 Agent 不是直接查文件,而是查「已治理過的組織知識」。實務上可以拆成三層:
- Raw Data Layer:原始文件、臨床試驗報告、SOP、法規文本。
- Semantic Memory Layer:針對每個實體建立結構化節點,例如:
DrugCandidate、ClinicalTrial、RegulatoryConstraint、RiskAssessment。- Governed Context Layer:每次 Agent 調用記憶時,同時附上:
- 來源追蹤(
source-link)。 - 認可版本(例如
SOP v3.2)。 - 責任人/審核狀態(已審核/草稿)。
好處:
- 生命科學與藥物研發高度受監管,機構記憶層就是你的合規邊界,能避免 Agent 誤用過期或未審核的資料。
- 在多代理場景中,所有 Agent 都從同一個治理過的記憶層取用上下文,避免「各自一套事實」。
💡 關鍵: 把資料拆成
raw / semantic / governed三層,等於在技術架構裡直接內建合規邊界與責任追溯能力。
3. 推理層治理:把「思考過程」變成可審核資產
37,000 Agent 能在一週分析 50,000+ 臨床試驗,真正需要治理的不是輸出,而是「決策鏈」。
所謂 reasoning-layer governance,核心是:
- 每個 Agent 的推理過程都要具備:
- 可結構化記錄:例如 chain-of-thought 的摘要,而不是一堆自然語言 log。
- 上下游關聯:知道這個結論引用了哪個前一步 Agent 的結果。
- 治理鉤子(hooks):可以插入審核、風險評估、
policy check。
在生命科學場景中,這直接對應到:
- 你能回答「這個臨床試驗設計,是基於哪些風險評估與模型輸出」。
- 審核者可以對整條推理鏈做
spot-check,而不是只看最後報告。
💡 關鍵: 把每一步推理結構化記錄並串成決策鏈,讓多代理系統不再是黑盒,而是可審核、可問責的工程資產。
實作範例
下面用一個簡化的「虛擬生技公司」示意多代理系統:
Orchestrator:負責任務分解與決策鏈管理。TargetAgent:負責藥物靶點鑑定。TrialDesignAgent:負責臨床試驗設計。GovernanceAgent:負責推理層治理與合規檢查。
1. Agent 設計與角色分工
# pseudo-code: Agent 定義

class BaseAgent:
    def __init__(self, name, llm_client, tools=None):
        self.name = name
        self.llm = llm_client
        self.tools = tools or []

    async def run(self, task, context):
        # task: 結構化的任務描述
        # context: 來自機構記憶的治理過資訊
        raise NotImplementedError


class TargetAgent(BaseAgent):
    async def run(self, task, context):
        prompt = f"""
        你是一位生物資訊學專家,負責藥物靶點鑑定。
        請在考慮以下已審核資料的前提下,提出 3 個候選靶點:
        {context['governed_knowledge']}
        任務描述:{task['description']}
        請輸出 JSON,包含: target_id, rationale, evidence_sources。
        """
        resp = await self.llm.chat_completion(
            model="gpt-5.6",
            messages=[{"role": "user", "content": prompt}],
            response_format={"type": "json_object"}  # **重要參數**
        )
        return resp


class TrialDesignAgent(BaseAgent):
    async def run(self, task, context):
        # 依據 TargetAgent 的輸出設計臨床試驗
        # context 中包含 target_candidates 與對應證據
        prompt = f"""
        你是一位臨床試驗設計專家。
        參考以下候選靶點與證據,設計一個一期臨床試驗:
        {context['target_candidates']}
        請輸出 JSON,包含: design_summary, inclusion_criteria, endpoints。
        """
        resp = await self.llm.chat_completion(
            model="gpt-5.6",
            messages=[{"role": "user", "content": prompt}],
            response_format={"type": "json_object"}
        )
        return resp
2. Orchestrator:任務編排與上下文治理
class Orchestrator:
    def __init__(self, memory_client, governance_agent):
        self.memory = memory_client  # 例如: **InstitutionalMemoryAPI**
        self.gov = governance_agent

    async def run_drug_program(self, program_id):
        # 1. 從機構記憶取得已審核上下文
        governed_ctx = await self.memory.get_context(
            entity_type="DrugProgram",
            entity_id=program_id,
            min_review_status="approved"  # **重要參數**
        )

        # 2. 呼叫 TargetAgent
        target_task = {"description": "為此適應症尋找新的靶點"}
        target_result = await TargetAgent.run(target_task, {
            "governed_knowledge": governed_ctx
        })

        # 3. 把推理層資訊寫入治理記錄
        await self.gov.log_reasoning_step({
            "agent": "TargetAgent",
            "input_context_id": governed_ctx["context_id"],
            "output": target_result,
            "program_id": program_id
        })

        # 4. 呼叫 TrialDesignAgent
        trial_task = {"description": "設計一期臨床試驗"}
        trial_result = await TrialDesignAgent.run(trial_task, {
            "target_candidates": target_result
        })

        await self.gov.log_reasoning_step({
            "agent": "TrialDesignAgent",
            "input_from_agent": "TargetAgent",
            "output": trial_result,
            "program_id": program_id
        })

        return {
            "targets": target_result,
            "trial_design": trial_result
        }
3. 推理層治理:審核與追蹤介面
class GovernanceAgent(BaseAgent):
    async def log_reasoning_step(self, record):
        # 寫入治理資料庫
        # 典型欄位: agent, input_refs, output_hash, risk_score, reviewer_required
        step = {
            "agent": record["agent"],
            "program_id": record["program_id"],
            "input_refs": {
                "context_id": record.get("input_context_id"),
                "from_agent": record.get("input_from_agent"),
            },
            "output": record["output"],
            "output_hash": hash(str(record["output"])),
            "risk_score": await self.assess_risk(record),  # **推理層治理**
        }
        # TODO: 寫入 DB
        return step

    async def assess_risk(self, record):
        # 基於使用的資料類型、適應症與試驗階段估算風險
        prompt = f"""
        你是一位合規與風險評估專家。
        請根據以下資訊評估此推理步驟的風險高低 (0-1):
        {record}
        只輸出一個浮點數。
        """
        resp = await self.llm.chat_completion(
            model="gpt-5.6",
            messages=[{"role": "user", "content": prompt}],
            temperature=0.0  # **重要參數:治理步驟建議設為 0**
        )
        return float(resp.choices[0].message.content)
這樣的實作讓每個 Agent 的輸出都被包裝成可追蹤的推理步驟,後續你可以做:
- 審核介面:按
program_id拉出整條推理鏈。 - 合規檢查:對高風險步驟強制需要人審或二次模型(
secondary model)覆核。
4. 避免「自我強化錯誤」的工具調用設計
自我強化錯誤(self-reinforcing error)的典型模式:
Agent A做出錯誤結論 → 寫入機構記憶 →Agent B引用成「既定事實」→ 再被更多 Agent 使用 → 錯誤逐步固化。
實務上可以在工具設計與決策鏈上加入 寫入前治理:
async def safe_write_to_memory(entity_type, payload, source_agent, gov_agent):
    # 1. 先用 GovernanceAgent 做一致性與風險檢查
    risk = await gov_agent.assess_risk({
        "agent": source_agent,
        "payload": payload,
        "entity_type": entity_type
    })

    if risk > 0.7:
        # 高風險內容不能直接寫入正式機構記憶,只能進入待審區
        return await memory_client.write(
            space="staging",
            entity_type=entity_type,
            data=payload,
            tags=["pending_review", f"source:{source_agent}"]
        )

    # 2. 低風險內容才寫入正式 space
    return await memory_client.write(
        space="governed",
        entity_type=entity_type,
        data=payload,
        tags=["approved_by_model", f"source:{source_agent}"]
    )
關鍵點:所有 Agent 的工具調用(尤其是寫入機構記憶)需經過治理層的 gate,不要讓 Agent 直接決定什麼變成「事實」。
建議與注意事項
1. 架構選擇
- 企業導入大規模 Agent,優先選擇:
- 集中式 Orchestrator + 去中心化記憶層:執行路徑單一,治理容易,但知識可以由多 Agent 持續補充(經治理
gate)。 - 若未來要轉向去中心化協作,預先:
- 把任務編排寫成顯式 DSL 或 workflow 定義,例如
YAML/JSON,而不是埋在程式邏輯裡,便於遷移到消息總線或Agent Mesh。
2. 資料來源與訓練數據合規
- 生命科學場景務必:
- 把資料切分成至少三個空間:
raw,staging,governed。 - 僅使用
governed空間當作 Agent 的主要上下文來源。 - 在 訓練數據 pipeline 也遵守同樣分層,避免未審核資料進入模型微調,導致系統性偏誤難以修正。
3. 工具調用與決策鏈上的坑
常見踩坑:
- 工具返回未標註來源:
- 坑:Agent 無法在推理層明確引用,導致理由模糊,人審時只能看「結果」,看不到「證據」。
- 建議:所有工具輸出都要包含
source_ids或evidence_links,並強制寫入治理記錄。 - 人類覆核與 Agent 推理混在一起:
- 坑:審核者會改結果但不改推理紀錄,造成
log與真實狀態不一致。 - 建議:人類操作也經由 Governance API,當成一個 reasoning step,留存審核意見與修改理由。
- 治理層模型溫度設置錯誤:
- 坑:合規模型溫度過高(如
0.7),同一樣本有不同評估結果,導致政策執行不一致。 - 建議:所有 reasoning-layer governance 模型呼叫,統一
temperature=0.0,確保可重現。
4. 對專案的實際好處
- 在生命科學或類似高監管場景中,導入上述架構與治理層,可以:
- 縮短研究與審核迴圈:讓
10+團隊共享同一套機構記憶與推理鏈路,不再重複爬資料與寫報告。 - 降低合規風險:每個模型決策都有清楚來源與風險標註,出事時可以追根究柢。
- 提高自動化上限:不是只自動化單一任務,而是可以安全地自動化整條藥物研發子流程,因為治理層為你兜底。
整體來說,37,000 Agent 的生命科學實驗案例把多代理系統從「酷炫 demo」拉到「可以被審核與問責的工程系統」。如果你要在企業內導入大規模 Agent,上面提到的 集中式 Orchestrator、機構記憶分層、推理層治理鉤子以及防自我強化錯誤的寫入 gate,是值得一開始就納入架構設計的核心元件。
🚀 你現在可以做的事
- 盤點現有內部系統,畫出一個集中式
Orchestrator+ 分層機構記憶的草圖架構- 在現有工具或 API 上,為所有「寫入知識庫」的操作加一層
GovernanceAgent風險評估 gate- 用一個小型專案(如單一產品線)試做
raw/staging/governed三層記憶與推理鏈記錄,驗證審核與追溯流程